
AI / ML
RAG Retrieval Optimization: Precision, Not Recall@K
An LLM's answer is set by the precision and order of its context, not by Recall@K. Retrieving more documents, badly ordered, makes RAG answers worse.
On machine learning, LLMs, and building applied AI systems, plus notes on the craft of engineering.
An LLM's answer is set by the precision and order of its context, not by Recall@K. Retrieving more documents, badly ordered, makes RAG answers worse.
An LLM bill is a product of a few factors, and input tokens re-read on every call dominate. The biggest wins are lossless discounts, not shaved output.
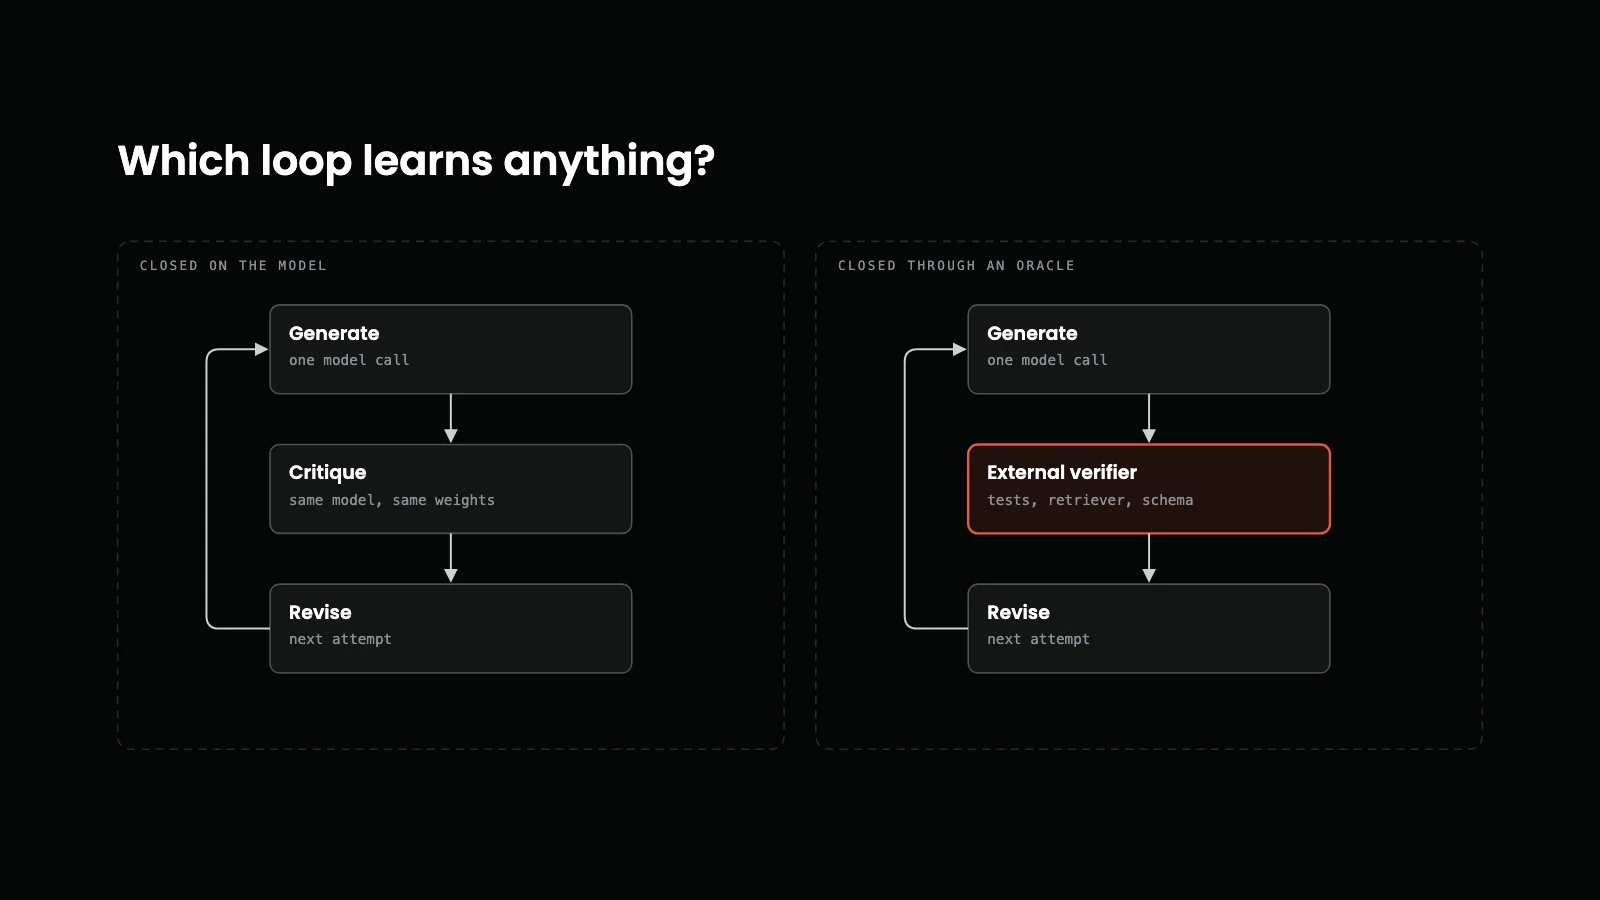
Self-correction degrades GPT-4 on GSM8K from 95.5 to 89.0. The agent patterns that work all share one thing: an oracle the model cannot fake.
ETL fails loudly; AI pipelines fail silently. Chunking and embedding destroy what you can audit, so contracts, quality gates and lineage must run upstream.
What LLM, MLM, SLM, LCM, MoE, VLM, SAM and LAM actually mean, how they differ, and why the eight names collapse into four design decisions.
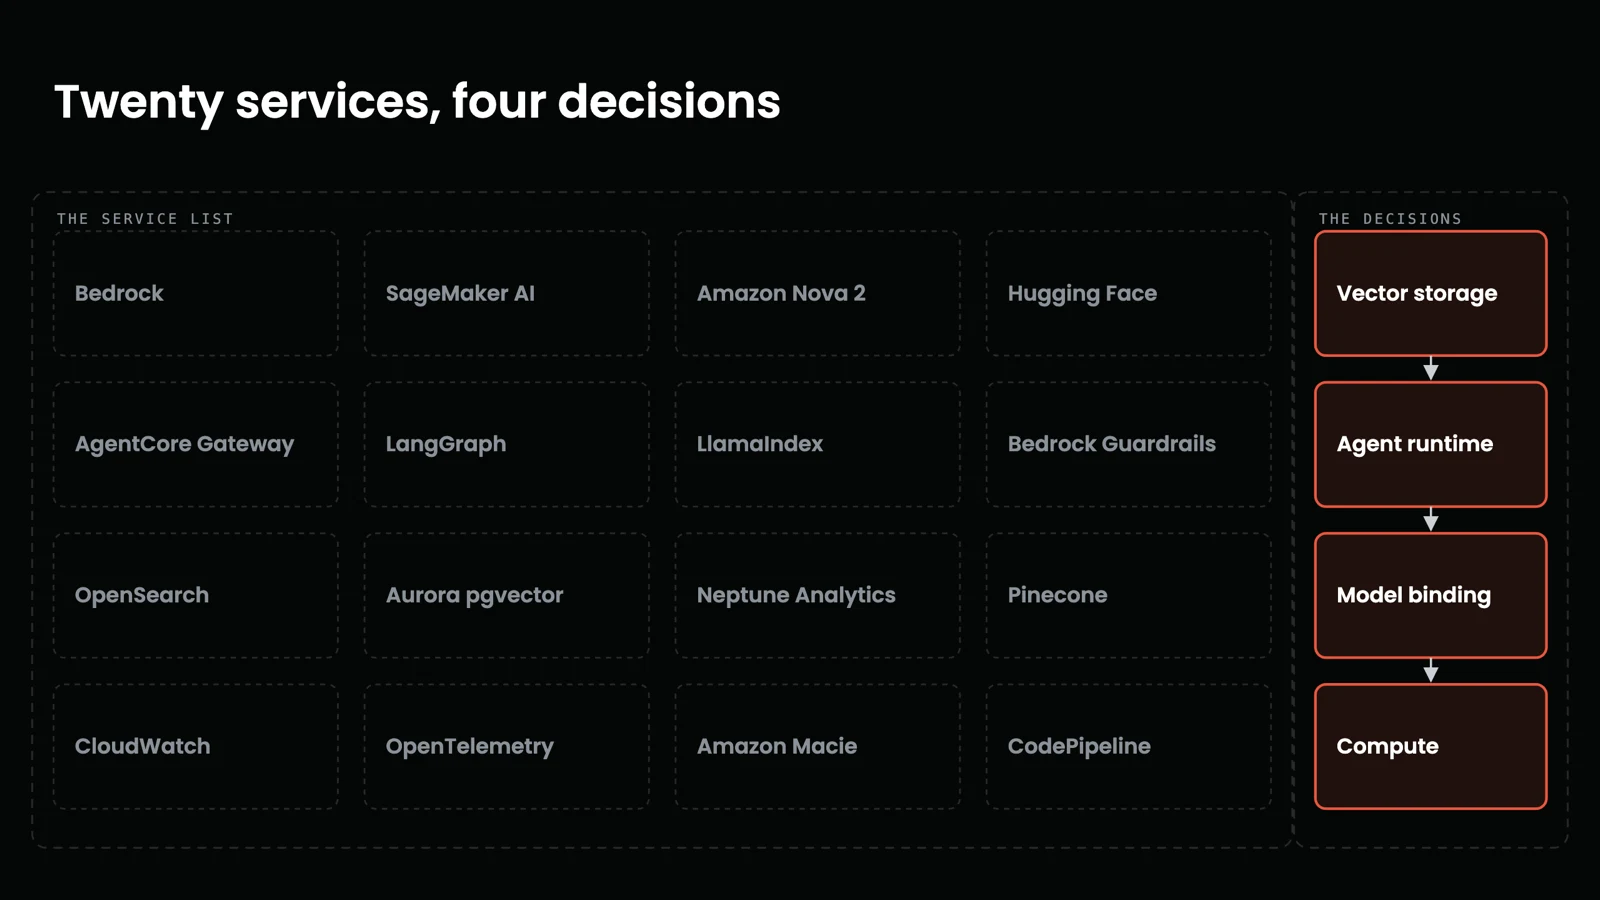
AWS now lists about ninety AI services. Four decisions determine the rest: vector store, agent runtime, model binding and the silicon underneath.